Folio — EditionSakina Saifuddin© 2026
2021

A journey through code, data, and intelligent systems.

Folio — EditionSakina Saifuddin© 2026
SS
01Intro02Work03What I Build04Achievements05Experience06Expertise07Contact
Case studyClick a page, swipe, or use ← → to turn

HEALTHCAREELIGIBILITY DATAPIPELINE

HEALTHCARE ELIGIBILITY

  • Collects eligibility data from many healthcare sources.
  • Merges it into one patient-level summary.
  • Validated field by field against the raw data.
20% → 80%validated data accuracy
~2 hrssaved per case
Visit the portfolio
website at:
sakina-saifuddin / works
24342
Healthcare EligibilitySakina Saifuddin
HEALTHCAREELIGIBILITY DATAPIPELINE

Many sources, one reliable summary
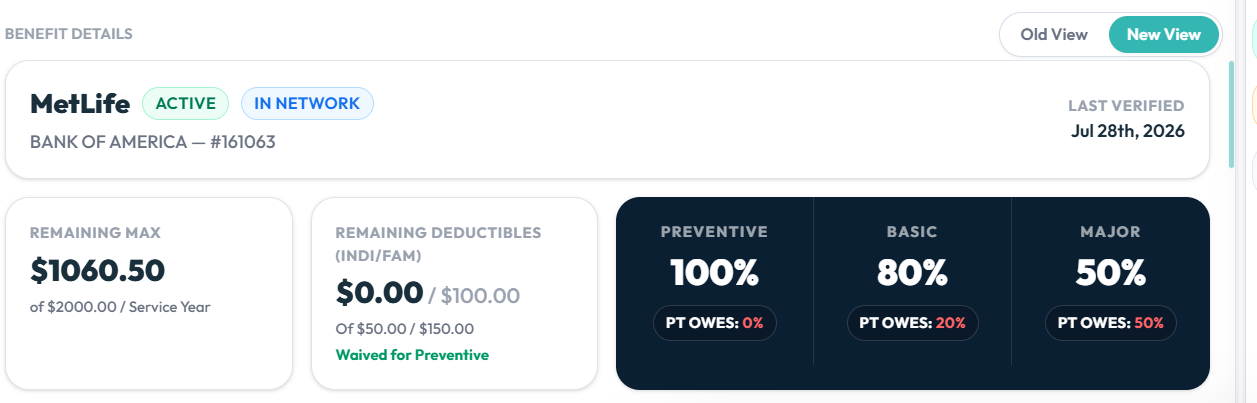
Fig. 1 — The classic Benefit Summary.1
  1. Task
  2. My work
  3. Results
  4. Outcome

Many sources, one reliable summary

  • Patient, insurance and benefit data lived in different systems.
  • Each payer could describe the same rule differently.
  • Staff needed one summary they could trust.
15–20data sources
2
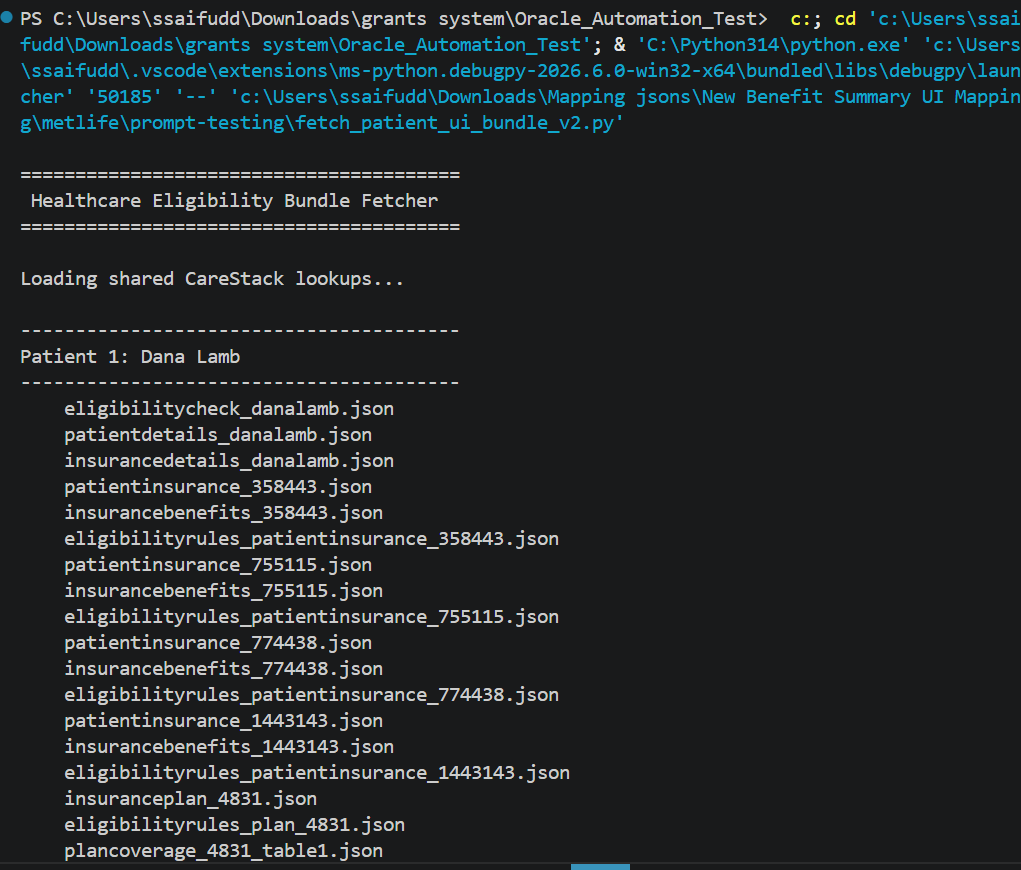
Every source in one bundle
Fig. 2 — The Python fetch workflow starting.3
  1. Task
  2. My work
  3. Results
  4. Outcome

Every source in one bundle

  • Collects patient, insurance, benefit and plan data.
  • Logs failed and empty responses for debugging.
  • Merges everything into one patient-level file.

Tools: Python · REST APIs · JSON

4
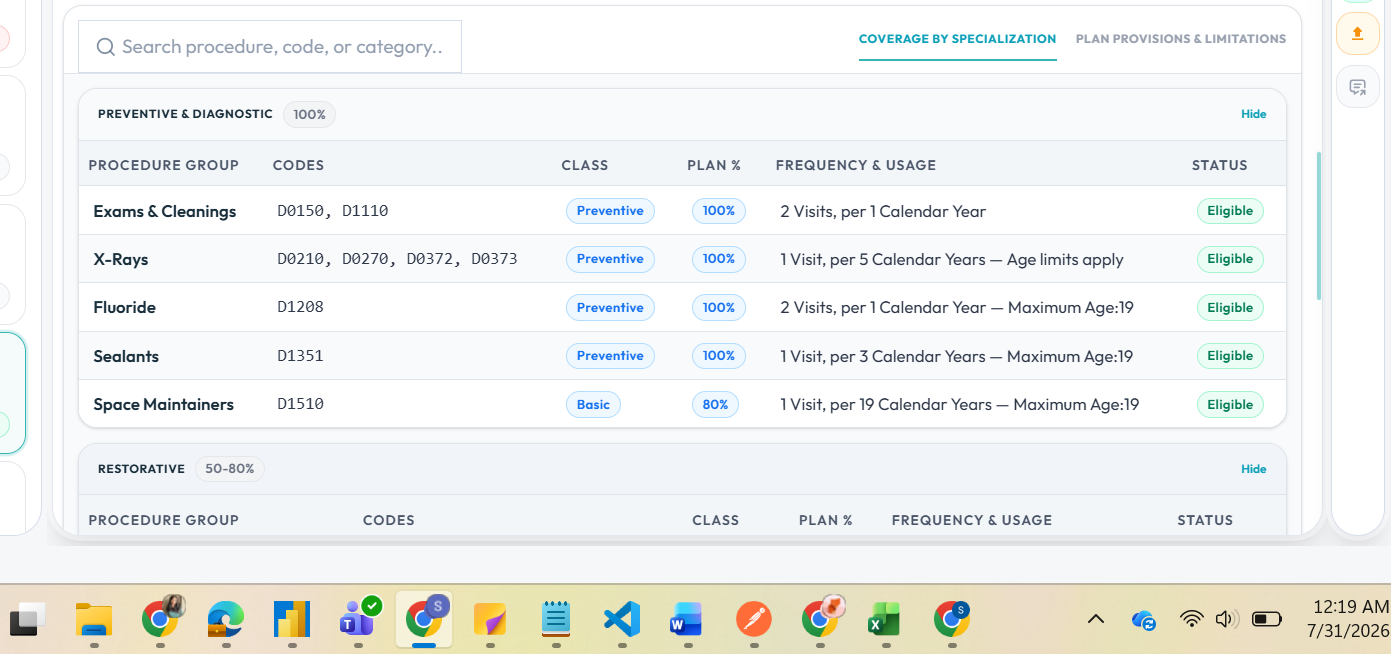
New screen checked against raw data
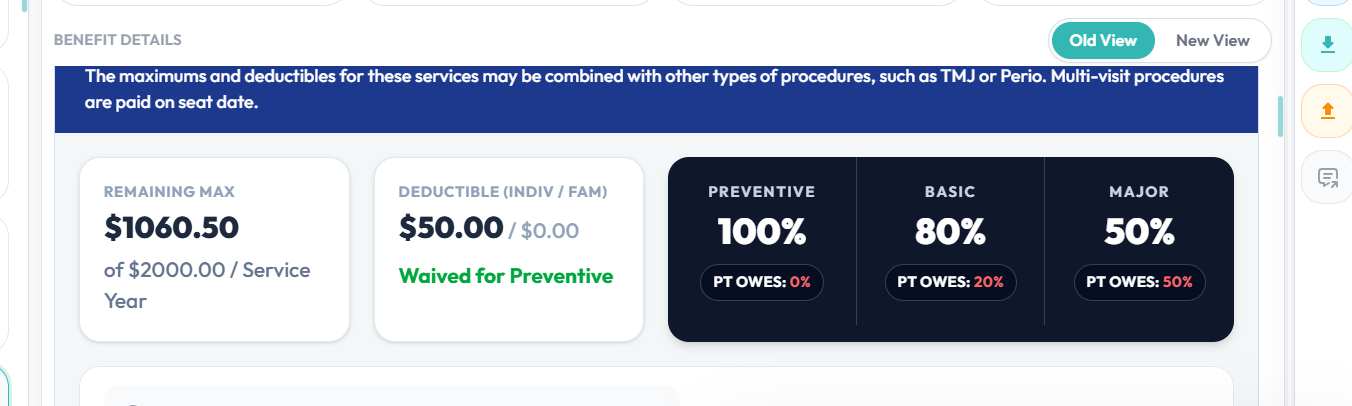
Fig. 3 — The new procedure view.5
  1. Task
  2. My work
  3. Results
  4. Outcome

New screen checked against raw data

  • Compared deductibles, maximums and coverage percentages.
  • Checked procedure codes and frequency limits.
  • Traced every mismatch back to the source.

Tools: Postman · SQL · BigQuery

6
Far more accurate, much faster
Fig. 4 — The redesigned Benefit Summary.7
  1. Task
  2. My work
  3. Results
  4. Outcome

Far more accurate, much faster

20% → 80%validated data accuracy
~2 hrsless manual lookup per case
15–20sources integrated
7deployments validated
8
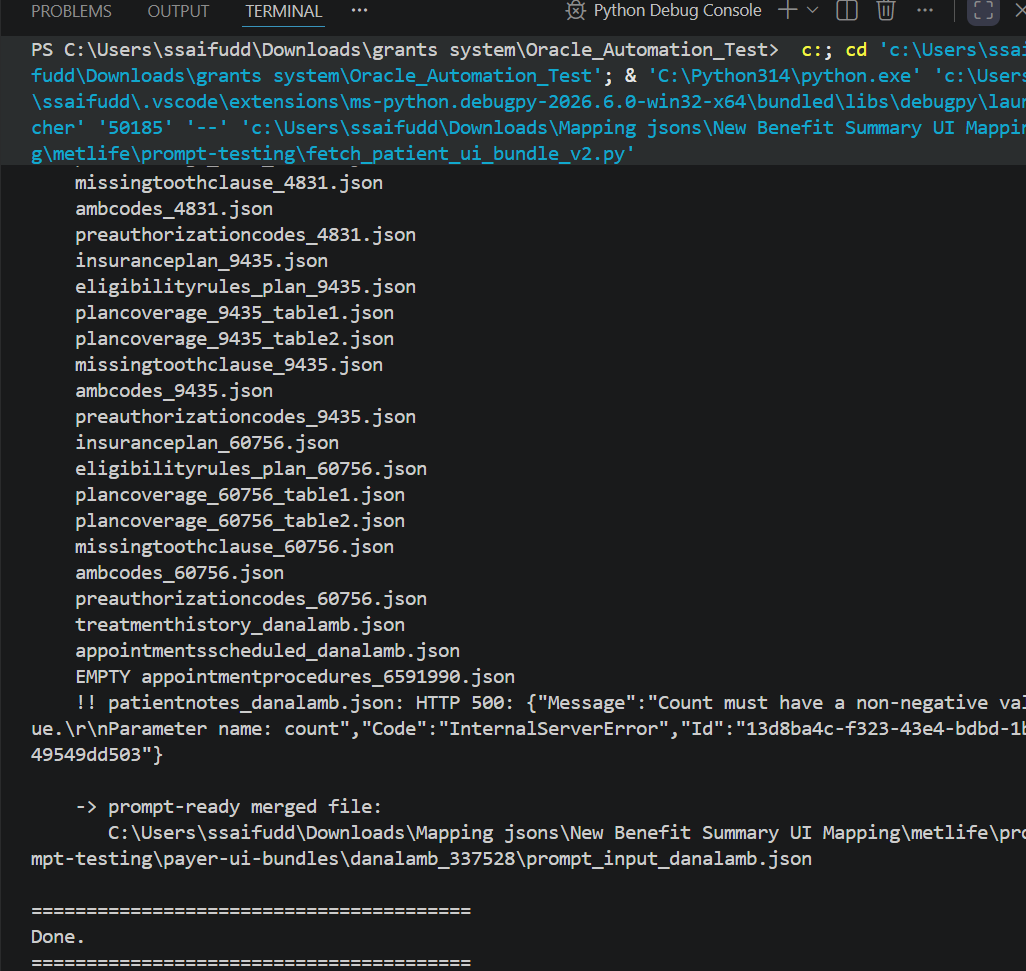
A summary staff can trust
Fig. 5 — One merged patient file per run.9
  1. Task
  2. My work
  3. Results
  4. Outcome

A summary staff can trust

  • Problems became clear mapping rules.
  • Manual lookups dropped sharply.
  • Public repo uses synthetic data only.
10
11

Technologies

Python
Fetching and merging.
REST APIs
DentalXchange and CareStack data.
SQL & BigQuery
Checking source data.
What I did
  • Built the Python fetch-and-merge workflow.
  • Wrote payer-specific mapping rules.
  • Validated the new screen field by field.
12

HEALTHCARE ELIGIBILITY

  • Collects eligibility data from many healthcare sources.
  • Merges it into one patient-level summary.
  • Validated field by field against the raw data.
20% → 80%validated data accuracy
~2 hrssaved per case
Visit the portfolio
website at:
sakina-saifuddin / works
24342
Cover